


Table of Contents
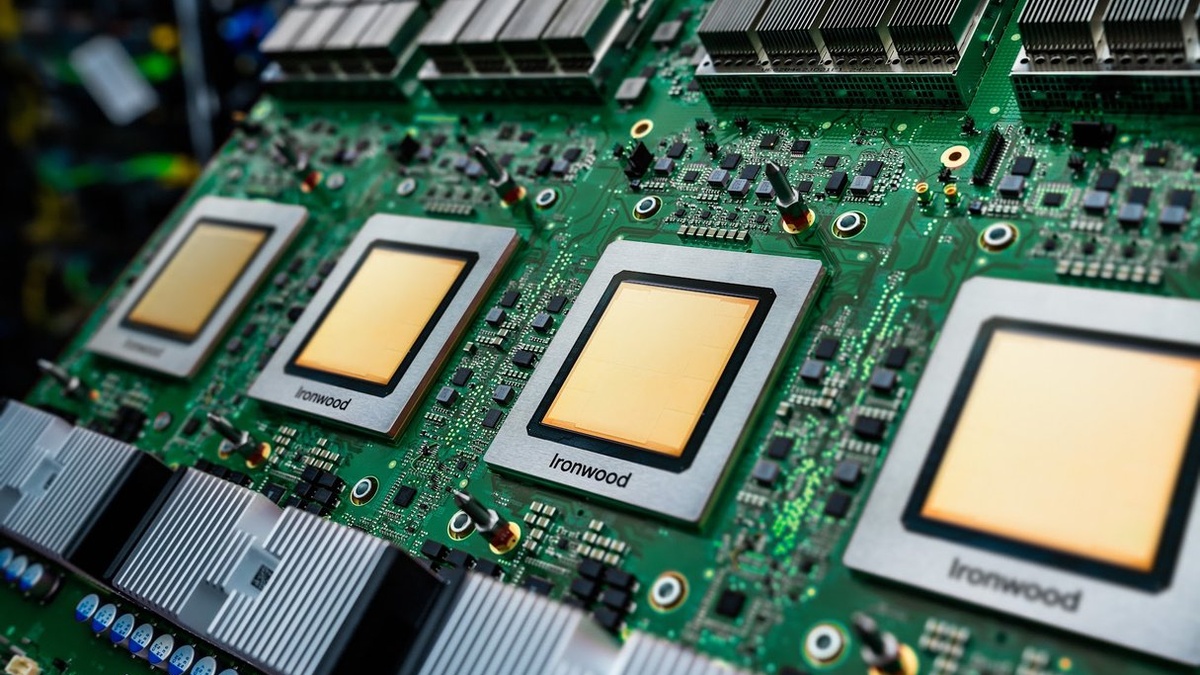
In the newly published Google Ironwood TPU Benchmarks, Google Cloud has unveiled unprecedented artificial intelligence training results across MLPerf Training v6.1, highlighting record-breaking model convergence speeds and massive hardware scaling across next-generation custom silicon.
Across these official Google Ironwood TPU benchmarks, the submissions demonstrate substantial velocity gains in frontier foundation model pre-training and agentic reinforcement learning, providing engineers with empirical proof of hyperscale co-design capabilities.
| Cluster Configuration | Accelerator Hardware | Cluster Scale | MLPerf Workload Domain | Convergence Time | Operational Metric |
|---|---|---|---|---|---|
| Google Ironwood Pod | Google TPU v7 (Ironwood) | 8,192 Accelerators | Frontier LLM Pre-Training | 1.70 Minutes | 96% scaling efficiency to 4,096 chips |
| Google Ironwood Cluster | Google TPU v7 (Ironwood) | 640 Accelerators | Agentic Reinforcement Learning (Coding) | 18.02 Minutes | 0.765 score (Goal: 0.69) with <3% chip idle wait |
| Google Cloud A4X Max | NVIDIA Grace Blackwell GB300 | 256 Accelerators | Frontier LLM Pre-Training | 31.96 Minutes | Full NVLink 5 domain coherence |
| Google Cloud A4X Instance | NVIDIA Grace Blackwell GB300 | Multi-Node Clusters | Agentic Reinforcement Learning | Verified Convergence | 5 compliant MLPerf Training submissions |
| AI Hypercomputer Fabric | Optical Circuit Switching (OCS) | Pod-Scale Fabric | Cross-Workload Pipelining | Sub-millisecond Reconfiguration | OpenXLA & JAX multi-framework pipeline |
MLPerf Training v6.1 Milestones: Seventh-Generation Ironwood Silicon
The publication of the MLPerf Training v6.1 suite establishes a critical inflection point for custom enterprise silicon, with Google Ironwood TPU benchmarks leading ten verified submissions across seventh-generation accelerators and NVIDIA Grace Blackwell architectures.
Developed entirely under Google Cloud’s AI Hypercomputer initiative, Ironwood represents a fundamental architectural overhaul optimized specifically for tensor operations, sparse matrix math, and high-bandwidth inter-chip memory exchanges during multi-modal training routines.
According to the official Google Cloud announcement, verified Google Ironwood TPU benchmarks reflect extensive co-design across silicon microarchitecture, optical interconnects, and compiler frameworks rather than isolated raw compute improvements.
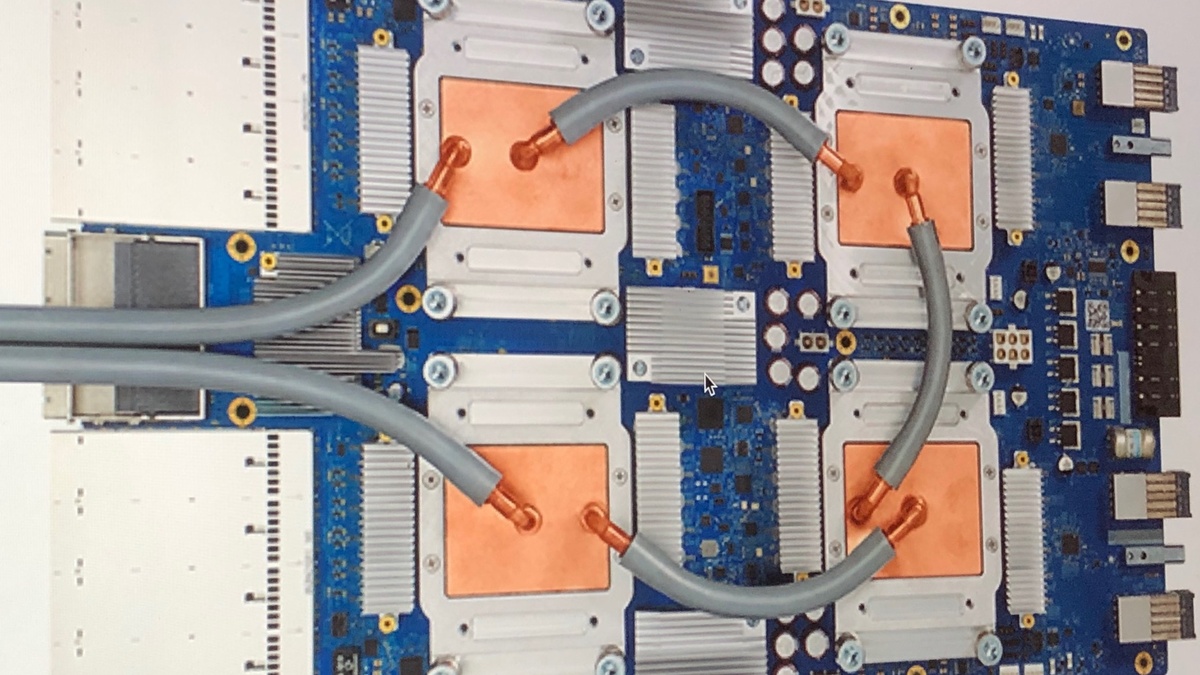
Much like how specialized silicon packaging revolutionized consumer chips in our AMD Ryzen 7 9800X3D architecture analysis, Ironwood leverages advanced thermal dissipation modules and direct liquid cooling substrates.
By moving beyond legacy monolithic chip designs, the seventh-generation Google Ironwood TPU benchmarks demonstrate how purpose-built machine learning accelerators drastically outpace generalized compute units across continuous distributed training cycles.
Frontier Pre-Training Velocity: 8,192-Chip Pods and Near-Linear Scaling
Scaling efficiency represents the supreme hurdle in modern foundation model development, and the latest Google Ironwood TPU benchmarks show an extraordinary ability to scale across 8,192 interconnected chips with near-linear performance gains.
During standardized frontier pre-training workloads, the Google Ironwood TPU benchmarks clocked an 8,192-chip cluster reaching target model quality in just 1.70 minutes, drastically compressing multi-week foundation model training cycles.
Remarkably, when scaling compute pods up to 4,096 chips, the Google Ironwood TPU benchmarks maintained an exceptional ninety-six percent scaling efficiency, proving that network serialization bottlenecks have been virtually eliminated at pod scale.
Engineers achieving this degree of cluster utilization depend on custom optical circuit topologies that bypass traditional electrical packet switching delays, enabling instant parameter broadcasting across thousands of matrix multiplication cores without dropped frames.
Such unprecedented scale mirrors the architectural leap observed when analyzing enterprise clusters in our cloud infrastructure scalability reports, where distributed throughput dictates real-world service economic viability.
Agentic Reinforcement Learning: Synchronous Generation Eliminates Compute Bubbles
A standout achievement within the latest Google Ironwood TPU benchmarks is the successful execution of the industry’s first standardized MLPerf benchmark designed specifically for agentic reinforcement learning workloads.
Agentic reasoning frameworks require models to iteratively generate reasoning tokens, validate programmatic code, and adjust internal policy weights in real time, historically creating massive idle latency bubbles across expensive accelerator clusters.
In these validated Google Ironwood TPU benchmarks, a cluster of 640 Ironwood accelerators achieved the coding target accuracy in 18.02 minutes, scoring 0.765 against the strict 0.69 MLPerf requirement.
Crucially, the Google Ironwood TPU benchmarks revealed that training accelerators waited less than three percent of total operating time, thanks to synchronized parallelization between live code generation and backward pass updates.
Eliminating compute pipeline starvation represents a monumental breakthrough for autonomous coding agents, ensuring that multi-turn reasoning models can train continuously without leaving costly silicon idle between simulation loops.
AI Hypercomputer Co-Design: Optical Circuit Switching and Software Stacks
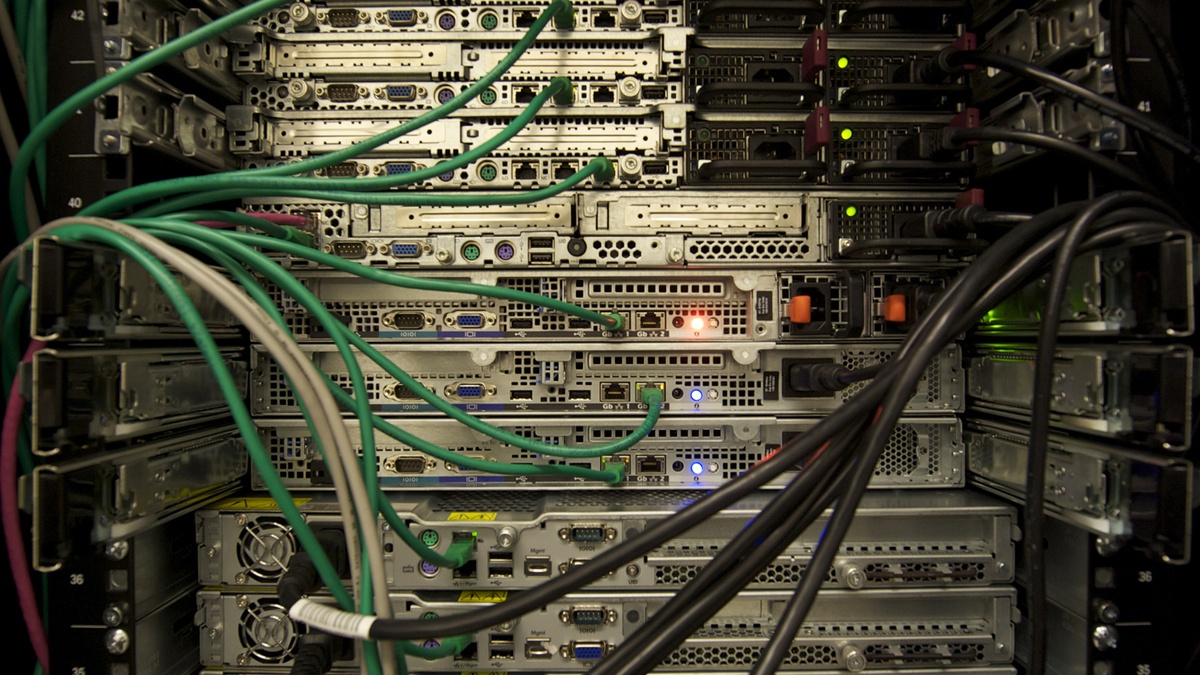
The underlying foundation enabling these Google Ironwood TPU benchmarks is Google Cloud’s AI Hypercomputer architecture, a deeply integrated systems paradigm that harmonizes physical accelerators, optical networking, and software compilation layers.
At the interconnect layer, Google deploys proprietary Optical Circuit Switches capable of reconfiguring cluster topologies dynamically, isolating failing nodes in milliseconds and preventing cluster-wide job terminations during massive multi-day training epochs.
On the software stack side driving the Google Ironwood TPU benchmarks, OpenXLA and JAX optimize computation graphs ahead of execution, generating parallelized machine kernels that maximize FLOP utilization across every core.
Similar full-stack integration principles were highlighted in our breakdown of custom Apple silicon unified memory architecture, where software-hardware synergy consistently outperforms raw transistor density alone.
By pairing native PyTorch and JAX support with reconfigurable optical fabrics, the Google Ironwood TPU benchmarks affirm Google Cloud’s commitment to delivering enterprise-grade flexibility without proprietary compiler lock-in.
Hardware Faceoff & Benchmark Analysis: Ironwood Versus NVIDIA Grace Blackwell
In addition to custom TPU submissions, the MLPerf suite provided direct comparisons with NVIDIA Grace Blackwell hardware hosted on Google Cloud A4X Max instances, highlighting contrasting design philosophies across top-tier accelerators.
While NVIDIA GB300 GPUs reached benchmark quality in 31.96 minutes, the comparative Google Ironwood TPU benchmarks highlighted distinct architectural tradeoffs between massive optical fabric scaling and high-density NVLink memory domains.
As we documented in our coverage of Nvidia’s strategic datacenter transitions, the company continues shifting development priorities toward high-margin enterprise AI accelerators like Grace Blackwell.
When evaluating the Google Ironwood TPU benchmarks against Grace Blackwell, organizations must weigh TPU raw pod scaling and optical switching advantages against Nvidia’s ubiquitous CUDA software ecosystem and generalized developer tooling.
According to detailed verification data logged by MLCommons MLPerf v6.1 results, both platforms set new industry records while serving distinct operational profiles across cloud infrastructure.
| Generational Specification | Google Cloud TPU v5p | Google Cloud TPU v6e (Trillium) | Google Cloud TPU v7 (Ironwood) | NVIDIA Grace Blackwell GB300 |
|---|---|---|---|---|
| Workload Optimization | Frontier LLM Pre-Training | Cost-Efficient Enterprise Inference | Agentic RL & Frontier Foundation Pre-Training | Hyperscale Multi-Modal AI Training & Reasoning |
| Interconnect Architecture | 4,800 Gbps 3D Torus ICI | 3,200 Gbps Dual-Ring ICI | Dynamic Optical Circuit Switched (OCS) Mesh | 1.8 TB/s NVLink 5 & Quantum-X800 InfiniBand |
| Maximum Pod Fabric | 8,960 Accelerators | 256 Accelerators | 8,192+ Accelerators per Optical Fabric | 576 GPUs per NVL72 Multi-Rack Domain |
| MLPerf v6.1 Benchmark Metric | Historical Reference | Inference Optimized Baseline | 1.70 min Pre-Training / 18.02 min Agentic RL | 31.96 min Pre-Training (256 GPUs) |
| Software & Compiler Support | JAX, TensorFlow, PyTorch | vLLM, TensorRT-LLM, OpenXLA | OpenXLA, JAX, PyTorch Native Pipelining | CUDA 12+, Megatron-LM, PyTorch, NeMo |
Frequently Asked Questions
The Enterprise AI Verdict: Custom Silicon Redefines Scaled Training
The release of the latest Google Ironwood TPU benchmarks cements Google Cloud’s position as a premier destination for hyperscale model training, proving that seventh-generation custom silicon delivers unmatched scaling efficiency.
By conquering the synchronization hurdles of agentic reinforcement learning, the latest Google Ironwood TPU benchmarks establish custom cloud silicon as a formidable technical counterweight to Nvidia’s dominant enterprise AI accelerator ecosystem.
As foundation models grow in complexity, the co-design breakthroughs validated across these Google Ironwood TPU benchmarks will drive the next era of supercomputing efficiency, transforming how enterprises train reasoning agents.
