


Table of Contents
At SC26, NVIDIA officially unveiled the NVIDIA Rubin HPC GPU, a breakthrough accelerator within the Vera Rubin supercomputing platform engineered to eliminate simulation bottlenecks, accelerate autonomous discovery agents, and deliver unprecedented computational density for modern science.
By scaling data movement in parallel with massive compute engines, the NVIDIA Rubin HPC GPU addresses complex molecular dynamics, climate projections, and numerical simulations that previously starved multi-thousand node clusters of continuous data.
| Platform Specification | NVIDIA Hopper H100 | NVIDIA Blackwell B200 | NVIDIA Rubin HPC Accelerator |
|---|---|---|---|
| Architecture Generation | Hopper Architecture | Blackwell Architecture | Vera Rubin Platform |
| Peak CUDA Cores | 16,896 Execution Cores | 20,848 Execution Cores | More Than 50,000 Cores |
| Interconnect Generation | NVLink 4 (900 GB/s) | NVLink 5 (1.8 TB/s) | Seventh-Generation NVLink |
| Memory Architecture | 80GB HBM3 Memory | 192GB HBM3e Memory | Next-Generation HBM4 Stacks |
| Sparse Data Engines | Sparse Tensor Core v1 | Sparse Tensor Core v2 | Dedicated Sparse Data Acceleration |
| Target Workload Focus | AI Training & Inference | Frontier Foundation Models | Agentic Science, Simulation & Analytics |
| Enterprise Availability | Commercial 2022 | Commercial 2024 | Expected 2028 |
SC26 Supercomputing Reveal: The Vera Rubin Platform Foundation
The annual Supercomputing Conference SC26 marked a pivotal milestone for scientific infrastructure with the debut of the NVIDIA Rubin HPC GPU, establishing a purpose-built architecture tailored directly to agentic modeling rather than generic matrix multiplications.
According to the official NVIDIA Blog announcement, the Vera Rubin platform represents an aggressive architectural leap that integrates Vera server processors, next-generation HBM4 memory stacks, and extreme bandwidth networking.
Hyperscale laboratories running molecular explorations have encountered persistent memory walls where raw compute capacity outpaces physical interconnect throughput, a critical bottleneck that the NVIDIA Rubin HPC GPU resolves through balanced system co-design.
Much like how innovative silicon packaging revolutionized consumer chips in our AMD Ryzen 7 9800X3D architecture analysis, NVIDIA Vera Rubin architecture combines dense liquid cooling and advanced multi-die packaging to sustain extreme workloads.
Slated for enterprise availability in 2028, the platform establishes a long-term roadmap for global research institutions requiring verifiable physical simulations before committing capital to multi-million dollar wet lab syntheses or physical wind tunnel tests.
Silicon Microarchitecture: Scaling Past 50,000 CUDA Cores
At the heart of the NVIDIA Rubin HPC GPU lies an astounding silicon achievement featuring more than 50,000 CUDA cores integrated onto a single package, representing the highest execution unit count ever engineered by NVIDIA.
Rather than merely duplicating compute blocks, chip designers restructured the underlying streaming multiprocessor pipelines to sustain maximum floating-point precision, ensuring consistent numerical stability across double-precision scientific algorithms and iterative partial differential equations.
This massive parallel execution fabric allows the NVIDIA Rubin HPC GPU to execute dense simulations simultaneously across thousands of spatial sub-domains, dramatically reducing wall-clock convergence times in computational fluid dynamics and astrophysics calculations.
Similar to modern architectural efficiency gains highlighted in our Apple M4 Pro silicon breakdown, thermal dissipation remains a critical engineering priority when scaling high-power execution pipelines across cutting-edge silicon dies.
Operating within custom liquid-cooled server enclosures, the NVIDIA Rubin HPC GPU optimizes per-watt computational throughput, enabling high-performance compute centers to maximize their compute density within existing electrical substation capacity.
Sparse Data Acceleration: Eliminating Compute Starvation in Complex Simulations
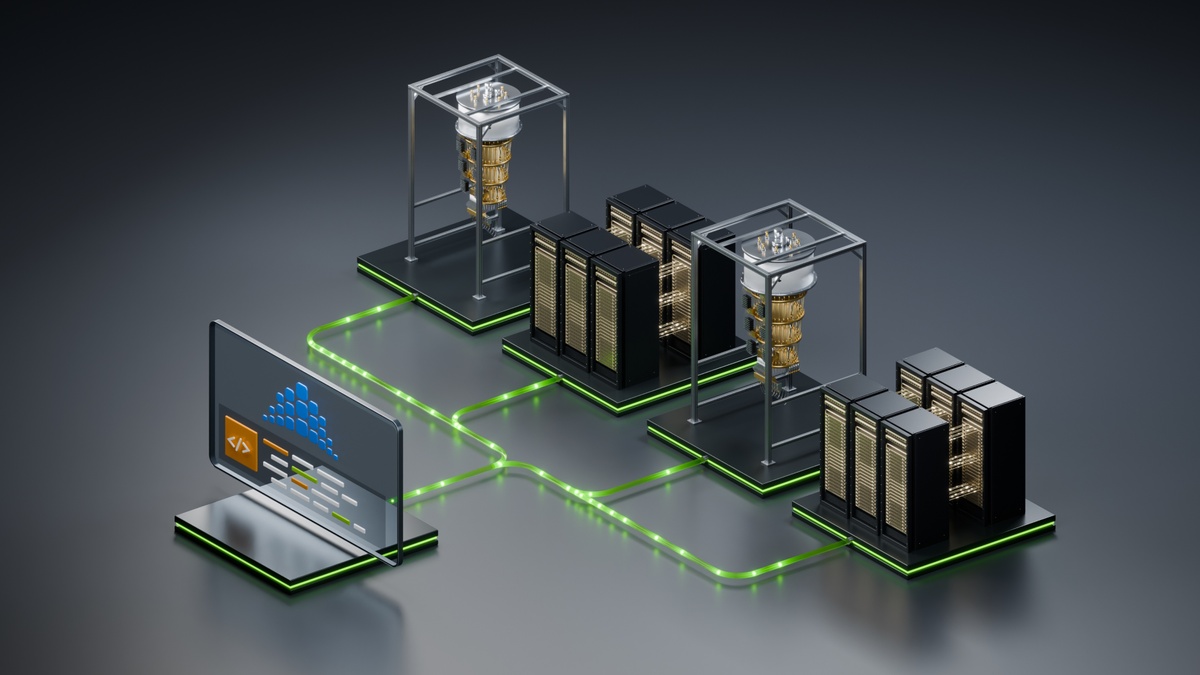
Raw core density offers little practical advantage if compute units spend clock cycles idling, which is why the NVIDIA Rubin HPC GPU incorporates specialized hardware engines designed explicitly for sparse data acceleration.
Scientific applications frequently touch sprawling datasets to extract scattered variables, creating irregular gather-scatter memory access patterns that typically overwhelm conventional GPU cache hierarchies during large-scale climate models and genomic population studies.
By managing dynamic memory routing at the hardware layer, the NVIDIA Rubin HPC GPU feeds its 50,000 CUDA cores with steady data streams, accelerating stencil operations, sparse matrix calculations, and parallel sorting routines.
This architectural balance ensures that simulation applications spend virtually all operational cycles calculating results rather than stalling for memory responses, yielding transformative throughput improvements across industrial structural analysis and material science.
Research teams executing billion-cell hydrodynamic models can therefore maintain high arithmetic intensity across the NVIDIA Rubin HPC GPU, shortening turnaround cycles from multi-week supercomputer reservations into manageable overnight exploratory runs.
Seventh-Generation NVLink Fabric: Coherent Multi-GPU Interconnects
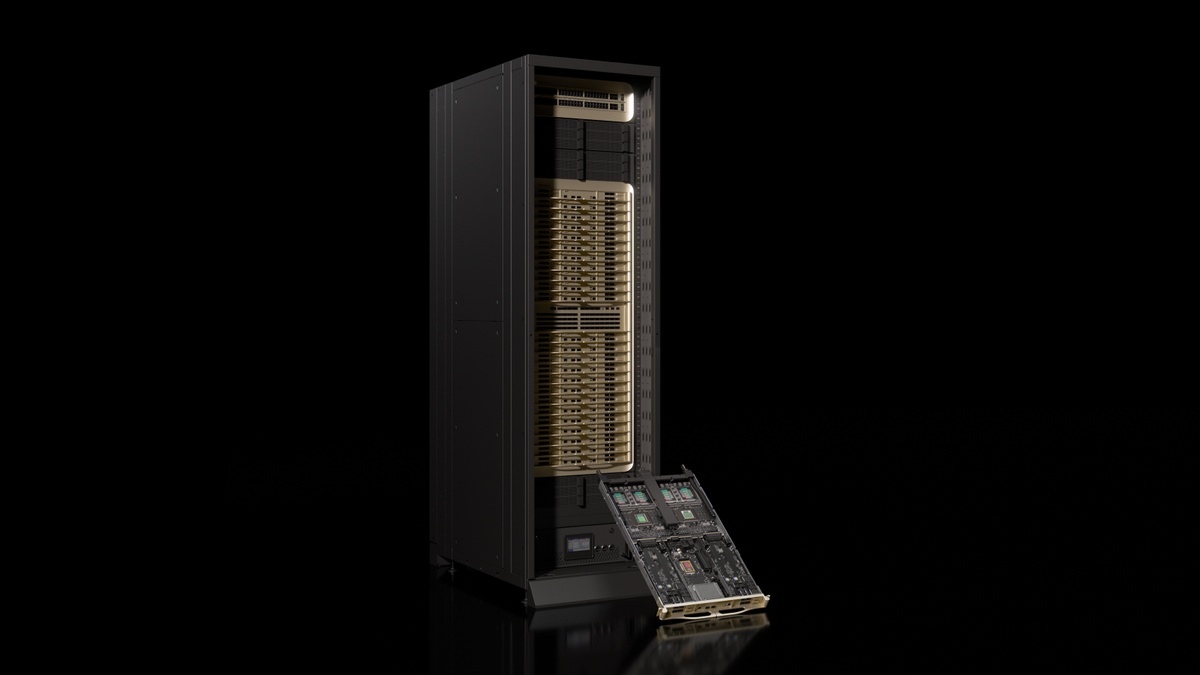
Scaling physical simulations across national laboratory clusters requires unprecedented interconnect bandwidth, a capability delivered by the NVIDIA Rubin HPC GPU through seventh-generation NVIDIA NVLink interconnect fabric.
NVLink 7 provides coherent GPU-to-GPU data transmission speeds that outpace legacy InfiniBand and Ethernet networks, linking multiple accelerators into a unified memory space with sub-microsecond latency across dense server trays.
As modern datacenters migrate to next-generation infrastructures as detailed in our cloud gaming datacenter analysis, ultra-dense GPU clustering demands low-latency fabric capable of handling massive cross-node gradient and boundary exchanges.
The NVIDIA Rubin HPC GPU leverages NVLink 7 to synchronize thousands of accelerator nodes without network-induced compute bubbles, enabling multi-physics solvers to exchange boundary conditions across distributed meshes instantaneously.
Through deep integration with NVIDIA Quantum InfiniBand switches, entire clusters of the NVIDIA Rubin HPC GPU function as a cohesive supercomputing fabric capable of scaling complex atmospheric and planetary simulations seamlessly.
Agentic AI for Science: Accelerating Discovery Loops in Material and Molecular Modeling
The emergence of autonomous artificial intelligence agents represents a profound paradigm shift, and the NVIDIA Rubin HPC GPU is specifically architected to serve as the high-speed simulation backbone for these reasoning workflows.
Instead of human researchers manually configuring every physical trial, autonomous software agents continuously propose candidate molecular structures, generate hypotheses, and immediately evaluate their feasibility against rigorous physical laws.
According to Ian Buck, vice president of hyperscale and HPC at NVIDIA, the NVIDIA Rubin HPC GPU accelerates agent-invoked simulations to rapidly shorten the cycle between initial hypothesis, digital validation, and experimental refinement.
Leveraging comprehensive NVIDIA CUDA-X software libraries, agents invoke physics solvers natively, evaluating thousands of therapeutic drug candidates or battery electrolyte formulations in parallel.
By collapsing validation loops from months into hours, the NVIDIA Rubin HPC GPU empowers research institutions to direct costly wet laboratory synthesis solely toward the most promising, digitally validated molecular candidates.
| Scientific Workload Domain | Core Computational Challenge | Rubin HPC Silicon Solution | Projected Operational Advantage |
|---|---|---|---|
| Molecular Dynamics | Non-bonded atom pair calculation latency | Hardware-accelerated sparse data engines | Eliminates execution idle bubbles |
| Climate & Weather Modeling | Memory bandwidth starvation on 3D stencils | High-bandwidth HBM4 memory subsystem | Sustains peak arithmetic intensity |
| Computational Fluid Dynamics | Cross-node boundary condition exchanges | Seventh-generation NVLink fabric | Near-linear scaling across thousands of nodes |
| Agentic Material Discovery | Iterative physics validation latency | Native CUDA-X simulation library integration | Shortens hypothesis feedback loops to hours |
| Genomic Population Analytics | Irregular gather-scatter memory access | Hardware-managed dynamic routing fabric | Accelerates variant association searches |
Frequently Asked Questions
What is the primary architectural purpose of the NVIDIA Rubin HPC GPU?
The NVIDIA Rubin HPC GPU is engineered specifically to accelerate scientific simulations, data analytics, and agentic discovery loops, pairing more than 50,000 CUDA cores with dedicated sparse data engines to prevent compute starvation.
How does sparse data acceleration benefit complex scientific simulations?
Sparse data acceleration optimizes irregular gather-scatter memory access patterns common in climate, genomic, and molecular workloads, ensuring that thousands of execution cores remain continuously supplied with simulation data without memory stalls.
What role does seventh-generation NVLink play in Rubin HPC clusters?
Seventh-generation NVLink delivers ultra-high-speed, low-latency GPU-to-GPU interconnect fabric, allowing thousands of accelerators to share a unified memory domain and exchange boundary mesh data without distributed networking bottlenecks.
How do autonomous AI agents interact with the Vera Rubin supercomputing platform?
Autonomous AI agents leverage NVIDIA CUDA-X libraries to invoke real-time physics simulations on the GPU, evaluating candidate materials and molecules iteratively to refine scientific hypotheses before physical lab synthesis.
When will the NVIDIA Rubin HPC accelerator be commercially available for enterprise datacenters?
NVIDIA announced at SC26 that the Rubin HPC accelerator is expected to become available to enterprise datacenters, research institutions, and cloud supercomputing partners beginning in 2028.
The Supercomputing Verdict: Rubin HPC Redefines Scientific Discovery
The announcement of the NVIDIA Rubin HPC GPU at SC26 marks a decisive transformation in supercomputing architecture, rebalancing computational power and memory throughput to meet the soaring demands of autonomous scientific discovery.
As legacy software models shift toward agentic reasoning and real-time physical verification—similar to broader transitions chronicled in our NVIDIA enterprise software transition coverage—purpose-built silicon represents the future of high-performance computing.
By pairing over 50,000 CUDA cores with NVLink 7 and sparse data engines, the NVIDIA Rubin HPC GPU provides the essential foundation for humanity next major scientific and engineering breakthroughs.
