


Table of Contents
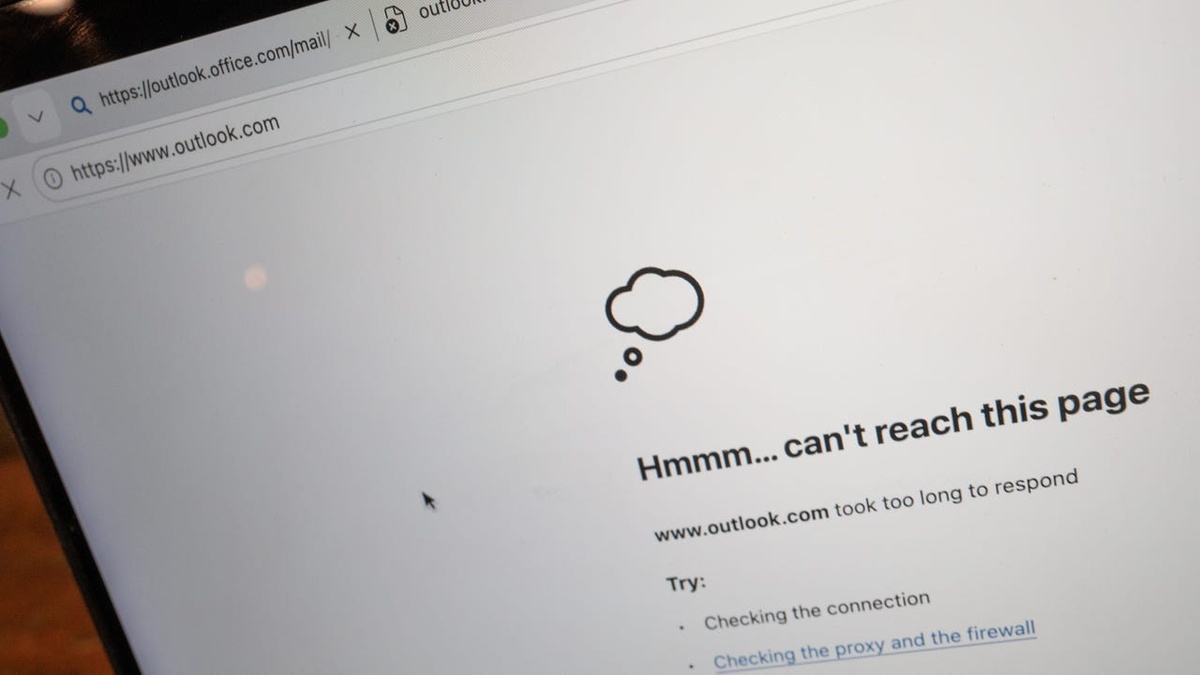
A prolonged systems disruption has crippled enterprise productivity across the world, triggering an unexpected Microsoft global system outage that severed access to Outlook email, Microsoft Teams collaboration channels, OneDrive document repositories, and Copilot AI services for over twelve continuous hours.
Rather than achieving rapid stabilization, Microsoft engineers admitted through official service channels that initial mitigation scripts failed to take hold, leaving administrators worldwide navigating sustained service degradation as remediations faltered across major regional availability zones.
| Enterprise Subsystem | Nominal Service Baseline | Outage Incident State | Primary Failure Trigger | Impacted Business Operations |
|---|---|---|---|---|
| Exchange Online Mail | Sub-second TLS routing | Global transport queuing halts | TLS handshake CPU exhaustion | Corporate email and calendar sync |
| Microsoft Teams Platform | Instant voice and chat | Session disconnects & errors | Upstream directory token latency | Enterprise meetings and channels |
| SharePoint & OneDrive | Real-time document sync | HTTP 503 file lockouts | Graph API gateway timeouts | Collaborative document editing |
| Microsoft Copilot AI | Interactive agent prompts | Model timeout failures | Semantic index unreachability | Enterprise generative AI tasks |
| Entra ID Directory | High-availability SSO | Authentication backlog spikes | Token validation throttling | Tenant single sign-on access |
Incident Escalation and Admissions: Why Early Mitigations Failed
When enterprise administrators first reported widespread connection drops early this morning, Microsoft acknowledged that severe capacity strains had paralyzed core infrastructure, transforming the incident into an exhausting Microsoft global system outage that disrupted tens of millions of professional seats globally.
As reported in breaking coverage from IGN, Microsoft confirmed that initial remediation scripts were not taking as expected, forcing engineering leadership to publicly concede that automated recovery workstreams had stalled.
“We have monitored the status of the changes applied to improve serviceability and confirmed they are not taking as expected,” Microsoft stated, acknowledging that severe traffic management imbalances defeated initial recovery scripts during the peak Microsoft global system outage.
The company confirmed that multiple core server clusters became unexpectedly unavailable simultaneously, severely degrading aggregate processing headroom and triggering cascading failover events rather than absorbing redirected enterprise client traffic through redundant backup routing layers.
Importantly, executive leadership moved quickly to quell fears of external sabotage, with Microsoft Executive Vice President Charles LaManna verifying that internal telemetry showed no evidence whatsoever of malicious cyberattacks or distributed denial of service intrusions.
Sustained Traffic Imbalances: The Capacity Bottlenecks Straining Exchange and Teams
Distributed cloud networks rely heavily on balanced ingress routing, but during this Microsoft global system outage, the sudden collapse of frontend nodes created extreme traffic management imbalances that defeated standard load-balancing algorithms across several primary Azure regions.
When key transport nodes dropped offline, active client connections were instantaneously redirected toward surviving cluster pools, causing those secondary servers to experience immediate memory exhaustion and CPU throttling under the intense connection flood.
Enterprise messaging queues inside Exchange Online rapidly backed up as incoming and outgoing mail transport agents failed to complete Transport Layer Security handshakes, leaving critical corporate correspondence stalled indefinitely in transmission buffers.
Telemetric incident graphs documented on Downdetector revealed massive complaint spikes spanning North America, Europe, and Asia Pacific, illustrating how thoroughly the Microsoft global system outage permeated regional corporate communication corridors throughout business hours.
While core Xbox gaming services avoided total disruption during this specific enterprise failure, workplace operations faced unprecedented paralysis as commercial tenants could neither verify scheduled calendar events nor exchange essential administrative messages.
Server Isolation and Traffic Carve-Outs: Containment Tactics at Hyperscale
Faced with ineffective hotfixes and mounting enterprise outrage, Microsoft cloud architects executed a drastic tactical shift to arrest the expanding Microsoft global system outage, opting to aggressively carve out compromised server nodes from the central production cluster entirely.
“We are aggressively pursuing all pathways to reduce impact,” Microsoft announced, confirming that engineering teams paused all scheduled code deployments, isolated damaged infrastructure nodes, and initiated systematic phased server reboots across affected global facilities.
Carving out damaged servers at hyperscale requires delicate traffic shaping, as abruptly isolating nodes can trigger catastrophic thundering herd reconnections if millions of queued endpoint clients attempt simultaneous handshakes with rebooting replacement hardware.
Engineers implemented strict ingress rate limiting at edge network boundaries, deliberately pacing authentication handshakes to ensure that rebooted transport clusters stabilized before absorbing active enterprise workloads during the ongoing Microsoft global system outage recovery phase.
This aggressive server isolation strategy gradually stemmed cascading crash loops, yet the sheer volume of queued transactional data meant that mail delivery backlogs took hours to drain safely across saturated enterprise tenants.
Cascading Ecosystem Dependencies: Copilot, Graph APIs and Authentication Stalls
The prolonged duration of the Microsoft global system outage starkly exposed the brittle architectural interdependencies governing modern Microsoft 365 cloud ecosystems, where a failure in directory or messaging microservices inevitably paralyzes ancillary platforms.
While collaborative applications like Microsoft Teams and SharePoint Online utilize distinct backend databases, their interactive web interfaces depend directly on shared Microsoft Graph application programming interfaces and central Entra ID authentication tokens.
When transport gateways degraded during the Microsoft global system outage, users found themselves locked out of collaborative documents, meeting agendas refused to synchronize, and AI assistants like Microsoft Copilot failed to process contextual prompts across tenant files.
| Mitigation Phase | Applied Engineering Action | Observed System Reaction | Mitigation Bottleneck | Operational Recovery Status |
|---|---|---|---|---|
| Phase 1: Rollback | Revert network telemetry update | Persistent server saturation | In-flight connection deadlocks | Failed: Mitigations not taking |
| Phase 2: Reboot | Cold restart of degraded clusters | Immediate health probe drops | Thundering herd reconnection flood | Failed: Rapid node crash |
| Phase 3: Carve-Out | Isolate damaged nodes from pool | Stabilized cluster core baseline | Temporary capacity headroom loss | Successful containment pass |
| Phase 4: Throttling | Enforce edge ingress rate limits | Gradual queue drainage achieved | Elevated client handshake delay | Active progressive recovery |
| Phase 5: Rebalancing | Reroute workloads across regions | Cross-region transit normalization | WAN link capacity utilization | Stabilized global operations |
Similar systemic platform dependencies have reshaped consumer technology workflows, as observed when hardware shifts forced migrations after NVIDIA ended Windows 10 support for PC gamers across legacy desktop setups.
Corporate IT departments testing high-density client hardware, including modern enterprise workstations like the Apple M4 Mac mini, were left powerless as cloud authentication gates stalled local productivity applications indefinitely.
By centralizing disparate productivity tools onto a single interdependent cloud fabric, the Microsoft global system outage effectively neutralized departmental workflows that conventional IT architectures historically isolated against shared points of operational failure.
Architectural Resilience and Disaster Recovery: Lessons for Enterprise IT
As corporate organizations tabulate the operational costs of this Microsoft global system outage, enterprise technology executives are confronting difficult questions regarding vendor concentration risk and the strategic necessity of maintaining redundant secondary communication pathways.
Relying exclusively on a single hyperscale cloud provider for email, identity federation, voice meetings, and document storage creates existential vulnerabilities when unexpected infrastructure incidents bypass regional high-availability safeguards.
Just as high-performance computing requires balanced microarchitectures without bandwidth bottlenecks, as demonstrated in our deep dive into the AMD Ryzen 7 9800X3D gaming processor, enterprise networks require decentralized resilience against single points of failure.
Furthermore, the fragility of centralized cloud hosting mirrors recurring reliability hurdles analyzed across Xbox cloud gaming pay-as-you-go infrastructure, where remote server congestion compromises interactive digital experiences.
Moving forward, resilient enterprise IT organizations must implement out-of-band communication networks, automated multi-cloud email relays, and offline document archives to safeguard business continuity against the next inevitable Microsoft global system outage.
Frequently Asked Questions
What caused the recent Microsoft global system outage across enterprise services?
Microsoft attributed the Microsoft global system outage to unexpected server unavailabilities that created severe traffic management imbalances, stressing remaining cloud infrastructure and causing cascading capacity bottlenecks across multiple regions.
Why did Microsoft state that initial outage repairs were not taking as expected?
Early configuration updates and capacity adjustments failed to relieve server congestion because persistent traffic imbalances and queued reconnection requests overwhelmed rebooted nodes before they could achieve operational stability.
Were Microsoft 365 services disrupted by a malicious cyberattack or DDOS event?
No, Microsoft Executive Vice President Charles LaManna explicitly verified that internal telemetry confirmed zero evidence of malicious activity, ransomware, or distributed denial of service attacks behind the outage.
Which major applications and services experienced downtime during the incident?
The disruption paralyzed Outlook email routing, Microsoft Teams collaboration channels, OneDrive and SharePoint document access, and Microsoft Copilot AI capabilities, though core Xbox gaming networks remained largely operational.
How can enterprise administrators protect operations during a Microsoft global system outage?
Organizations should deploy secondary asynchronous email gateways, maintain air-gapped local backups of essential files, and establish independent messaging channels to preserve vital communication during a Microsoft global system outage.
Final Verdict: Navigating Hyperscale Cloud Fragility
The disruptive severity of this Microsoft global system outage serves as an urgent wake-up call for global organizations that have traded architectural independence for the operational convenience of centralized hyperscale cloud software.
While Microsoft eventually stabilized infrastructure through aggressive node carve-outs and edge rate limiting, the admission that initial hotfixes failed highlights the terrifying complexity of managing distributed distributed systems under unexpected load.
Enterprise technology leaders must treat this Microsoft global system outage as a catalyst to audit single-vendor dependencies, enforce rigorous disaster recovery protocols, and implement resilient multi-cloud contingency frameworks.
