


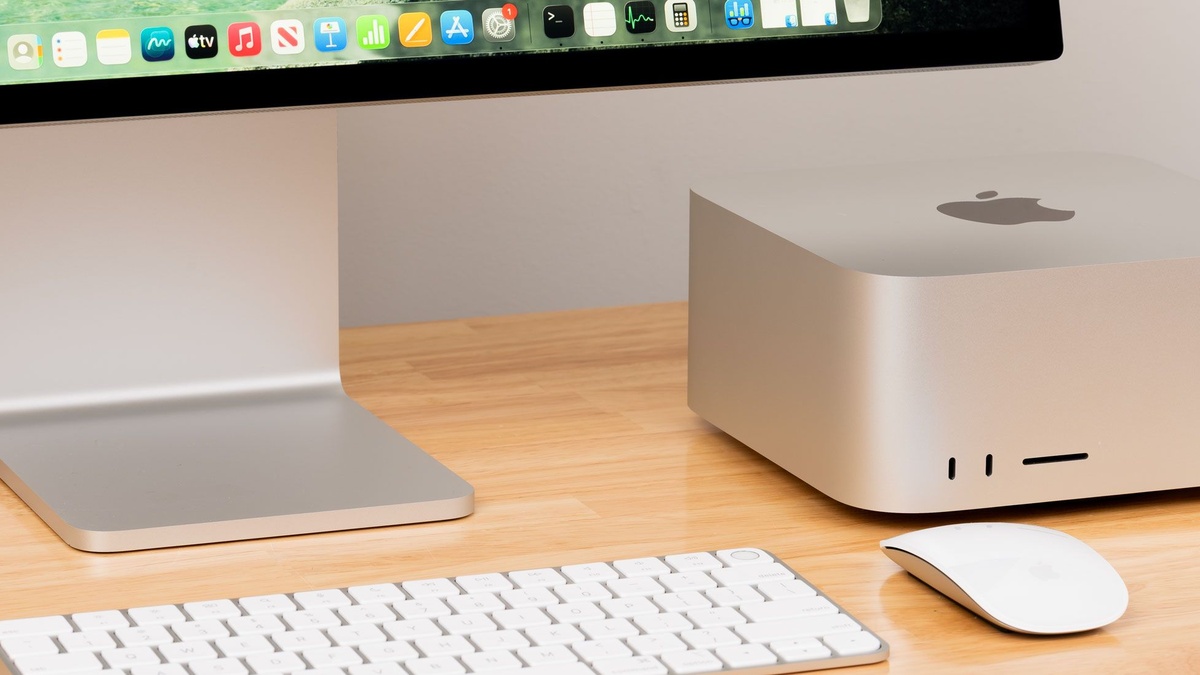
In-depth hardware testing has unveiled how Apple’s flagship Mac Studio M5 Ultra performs against Nvidia’s DGX Spark platform, providing engineers with empirical data on memory bandwidth, prompt processing, and power efficiency across demanding local generative artificial intelligence workloads.
According to a comprehensive benchmark suite published by Tom’s Hardware, running frontier large language models locally reveals striking architectural trade-offs between monolithic unified memory and specialized clustered enterprise silicon.
| Hardware & AI Benchmark Metric | Apple Mac Studio M5 Ultra | Nvidia DGX Spark (Dell Pro Precision GB10) |
|---|---|---|
| Compute Engine Architecture | 36-Core CPU & 80-Core GPU with Neural Accelerators | Single Grace Blackwell Superchip (48 Blackwell SMs) |
| Memory Configuration | 256GB Unified Memory Architecture (Up to 512GB) | 128GB Unified LPDDR5x (Requires dual cluster for 256GB) |
| Memory Bandwidth | 1.2 TB/s unified memory bandwidth | 273 GB/s decode bandwidth per node |
| AgentPerf-Local Completion | Finished benchmark in under half the total time | Baseline reference runtime on single Spark node |
| Task Energy Efficiency | Consumes 16% less task energy in kilojoules | Standard reference power draw under sustained compute |
| Energy-Delay Product (EDP) | Under half the EDP of single DGX Spark | Baseline reference energy-delay product |
| GLM 5.3 Flash (TensorFold MLX) | 3x faster decode throughput than standard llama.cpp | Faster prompt ingestion via multi-node cluster |
| DeepSeek V4.1 Flash (2-bit) | Fits 256GB natively; llama.cpp prompt ingest lags | Clustered Sparks digest long context in under 5 minutes |
| Primary Inference Stack | Apple MLX, llama.cpp, TensorFold | Nvidia CUDA, TensorRT-LLM, TensorFold |
| Turnkey System Pricing | $12,300 as tested (Single compact workstation) | $10,000 single node / $15,000–$20,000+ dual cluster |
Table of Contents
1. Unified Memory vs Clustered VRAM: The $10,000 Local AI Hardware Divide
Building an on-premises artificial intelligence workstation in 2026 requires navigating an aggressive pricing landscape, where deploying the Mac Studio M5 Ultra challenges traditional multi-GPU desktop clusters through integrated silicon design.
Apple equips this workstation with a massive 36-core central processor and an 80-core graphics engine, coupled with dedicated matrix math neural accelerators designed specifically to accelerate transformer inference.
Crucially, the desktop supports up to 512 gigabytes of unified system memory operating across an extraordinary 1.2 terabytes per second of shared memory bandwidth, eliminating conventional PCIe bus bottlenecks.
By contrast, Nvidia targets enterprise developers with the DGX Spark platform, powered by Dell Pro Precision GB10 systems that integrate 48 Blackwell streaming multiprocessors alongside 128 gigabytes of fast memory.
While a single DGX Spark provides exceptional CUDA acceleration, running massive parameter weights locally often forces developers to cluster multiple nodes together, elevating costs well above a single Mac Studio M5 Ultra setup.
Engineering teams exploring desktop workstation form factors can observe similar high-density packaging trends in our deep dive into the Apple M4 Mac Mini redesign across consumer desktop silicon.
2. AgentPerf-Local Benchmarks: M5 Ultra Outpaces Single DGX Spark in Efficiency
To assess real-world responsiveness, engineers executed the Artificial Analysis AgentPerf-Local benchmark suite, replaying rigorous multi-step agentic traces using the dense Qwen 3.8 27B model.
Because agentic workflows demand heavy prompt processing before token generation begins, hardware architectures with superior raw matrix compute and expansive memory throughput maintain a substantial operational advantage.
In direct head-to-head evaluation, the Mac Studio M5 Ultra completed the full agentic benchmark suite in just under half the time required by a standalone DGX Spark workstation.
Beyond pure completion speed, wall-socket power measurements revealed that Apple’s machine consumed approximately 16 percent less overall task energy in kilojoules throughout the identical computational workload.
Calculating the energy-delay product by multiplying execution duration with total energy consumption showed the Mac Studio M5 Ultra achieving an efficiency rating under half that of the competing Blackwell platform.
These findings prove that Apple’s massive memory bus delivers remarkable thermodynamic efficiency when executing localized agentic loops that do not exceed single-chassis memory limits.
3. The Software Recipe Bottleneck: Why MLX Stack Maturity Dictates Real-World Speed
Despite commanding raw hardware advantages in memory bandwidth and energy conservation, real-world deployment performance on Apple Silicon remains heavily dependent on runtime software stacks and custom inference compilation recipes.
The open-source Apple MLX framework continues to mature rapidly, but the broader developer ecosystem still leans heavily toward CUDA-optimized deployment pipelines developed over decades.
When researchers rely solely on standard llama.cpp runtimes without platform-tailored kernels, the Mac Studio M5 Ultra leaves substantial hardware throughput unutilized, leading to sluggish prompt digestion during complex prompts.
Nvidia benefits from comprehensive developer optimization, where mature serving recipes dynamically leverage advanced speculative decoding and tailored tensor parallelism out of the box.
Consequently, maximizing the computational potential of Apple’s flagship workstation requires specialized software configurations, proving that high memory bandwidth cannot fully compensate for unoptimized inference kernels.
As corporate IT departments modernize development infrastructure, similar operational considerations arise when managing legacy platforms, as explored in our report on Nvidia ending Windows 10 support.
4. DeepSeek V4.1 Flash and GLM 5.3: Speculative Decoding & TensorFold Scaling
Evaluating cutting-edge frontier architectures like DeepSeek V4.1 Flash 1017 and GLM 5.3 Flash illustrates where the Mac Studio M5 Ultra triumphs and where software friction emerges.
The 256-gigabyte memory pool of Apple’s flagship workstation enables it to load a two-bit quantization of DeepSeek V4.1 Flash directly into local RAM without requiring distributed network clustering.
However, due to current memory headroom constraints in llama.cpp, the Mac cannot simultaneously host the necessary speculative drafting model, forcing unaugmented token decoding that requires up to 25 minutes for long context ingestion.
| Target Model Architecture | Apple Mac Studio M5 Ultra Configuration | Nvidia DGX Spark Clustered Setup | Inference Execution Outcome |
|---|---|---|---|
| Qwen 3.8 27B (Dense) | llama.cpp with Native MTP enabled | Single Spark GB10 via llama.cpp | Mac finishes in under half the time with 16% lower task energy |
| GLM 5.3 Flash (4-Bit) | TensorFold MLX optimized recipe | Dual DGX Spark cluster via Mia’s AI recipe | Mac achieves 3x faster token decode throughput via 1.2 TB/s bus |
| DeepSeek V4.1 Flash (2-Bit) | llama.cpp single-node (No draft model) | Dual Spark cluster with DSpark speculative decoding | Spark cluster ingests long prompts in under 5 minutes vs 25 min on Mac |
| Llama 3.3 70B (Instruct) | Native MLX 4-bit quantized engine | Single Spark GB10 via TensorRT-LLM | Parity decode speed; Mac offers broader local context headroom |
| Multi-Agent Tool Traces | AgentPerf-Local execution pipeline | Clustered Blackwell SM nodes | Mac delivers superior Energy-Delay Product across local tasks |
In stark contrast, a clustered dual-Spark configuration utilizing the TensorFold inference engine and DSpark speculative decoding digests identical long-context prompts in under five minutes.
When paired with tailored serving recipes for GLM 5.3 Flash, however, the Mac Studio M5 Ultra demonstrates astounding capabilities, tripling decode throughput over standard runtimes.
Just as competitive gaming platforms require tuned processing silicon, as seen with the AMD Ryzen 7 9800X3D gaming CPU, local neural networks require specialized inference compilation to unleash peak silicon output.
5. Enterprise TCO and Hardware Scalability: Evaluating the $12,000 Investment
Financial considerations heavily influence enterprise hardware selection, where a fully configured Mac Studio M5 Ultra retailing around $12,300 presents an intriguing value proposition against escalating enterprise memory prices.
Severe global supply crunches across high-density DRAM and NAND flash storage have caused individual Dell Pro Precision GB10 systems to exceed $10,000 each on commercial distributor channels.
Assembling a functional dual-Spark cluster capable of matching Apple’s 256-gigabyte memory capacity pushes total procurement costs between $15,000 and $20,000, representing a significant price premium.
For private research teams seeking a quiet desktop workstation that doubles as a world-class development machine, the Mac Studio M5 Ultra provides unrivaled acoustic comfort and physical elegance.
While decentralized cloud services expand rapidly, as highlighted in our coverage of Xbox Cloud Gaming pricing bundles, maintaining completely private on-premises weights remains essential for corporate compliance.
Nevertheless, teams prioritizing immediate out-of-the-box model compatibility and rapid Hugging Face integration may still justify investing in Nvidia clusters despite the substantial price disparity.
Frequently Asked Questions
How does the Mac Studio M5 Ultra perform against Nvidia DGX Spark in local AI?
The Mac Studio M5 Ultra completes agentic tasks like AgentPerf-Local in under half the time of a single DGX Spark, while consuming 16 percent less task energy and cutting the energy-delay product by more than half.
Why are custom software inference recipes necessary for Apple Silicon?
Standard runtimes like llama.cpp often underutilize the memory bandwidth of the Mac Studio M5 Ultra, whereas tailored frameworks like TensorFold and MLX boost token decode throughput by up to three times on compatible models.
Can the Mac Studio fit large models like DeepSeek V4.1 Flash locally?
Yes, the 256GB unified memory configuration of Apple’s flagship workstation fits quantized versions of DeepSeek V4.1 Flash, though running speculative drafting models simultaneously requires specialized software optimizations.
What is the pricing difference between Apple’s flagship workstation and Nvidia DGX Spark clusters?
A tested 256GB Mac Studio M5 Ultra costs approximately $12,300, whereas building an equivalent 256GB dual-node Nvidia DGX Spark cluster exceeds $15,000 to $20,000 due to enterprise hardware and memory supply pressures.
Who should buy Apple’s flagship workstation for artificial intelligence workloads?
The Mac Studio M5 Ultra is ideal for developers and researchers seeking an efficient, whisper-quiet unified workstation capable of running large models, provided they leverage optimized MLX and TensorFold serving stacks.
Final Verdict: Balancing Raw Apple Silicon Power Against Nvidia Ecosystem Maturity
The Mac Studio M5 Ultra solidifies Apple Silicon as a legitimate powerhouse for on-premises artificial intelligence, delivering unprecedented memory density, class-leading thermal efficiency, and breathtaking agentic performance within a compact chassis.
While Nvidia retains a decisive advantage in software maturity, speculative decoding ecosystems, and turnkey model support, Apple’s architectural design narrows the capability gap faster than many enterprise observers anticipated.
For engineering laboratories willing to leverage modern MLX compilation stacks, investing in the Mac Studio M5 Ultra delivers extraordinary local inference capabilities at a substantially lower total cost than clustered enterprise rivals.
